Worked example: image in, text out
This sample card uses clear Urdu print (plus one English line). Load a similar photo in the tool above with language set to Urdu. Your output should resemble the block below when the source is sharp. Real Nastaliq pages will need more editing; that is expected for best-effort Urdu OCR.
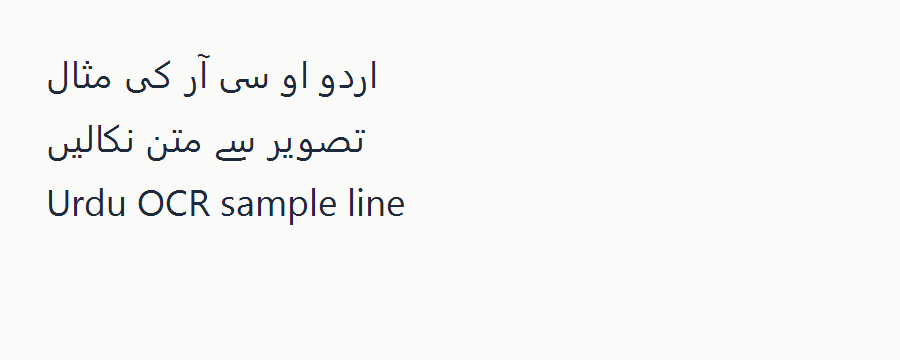
Expected OCR output (approx.):
اردو او سی آر کی مثال
تصویر سے متن نکالیں
Urdu OCR sample line
Online Urdu OCR that stays on your device
People searching urdu image to text or image to text Urdu usually need editable اردو from a book page, form, or sign. Photo2Text runs Tesseract in the browser: pick Urdu, click Extract, and edit the result locally. Privacy is real; accuracy is honest best-effort.
Accuracy notes for Urdu OCR
- Printed pages beat handwriting and heavy Nastaliq ornament.
- Fill the frame with text; crop stamps and busy backgrounds.
- Hold the phone parallel to the page to reduce warp.
- Use English + Urdu only when both scripts share the crop.
- Proofread before you paste into important documents.
Deeper prep checklist: Urdu OCR tips.
Nastaliq vs Naskh: why the font decides the result
Urdu print uses two very different styles, and knowing which one you are looking at sets your expectations. Nastaliq is the traditional style of Urdu books, newspapers, and poetry. Its letters slope downwards from right to left, words stack on top of each other, and a single word can rise and fall across a large vertical space. It is beautiful on the page and demanding for a machine, because the engine must untangle overlapping shapes that do not sit on one straight baseline. Naskh is the upright style used in many school books, official forms, and modern digital text. Its letters sit on a clear baseline with even spacing, much like the Arabic Naskh used in Arabic books, and OCR engines handle it far better.
Before you run OCR, look at the page and name the style. A newspaper front page, a poetry collection, or an old novel is usually Nastaliq, so expect a useful draft that needs editing rather than a clean copy. A government form, a school textbook, or a typed letter is more often Naskh, so a sharp photo should give a much cleaner result. If a page mixes the two, for example a Naskh form with a Nastaliq heading, run the body first and type the heading yourself. Splitting the work this way keeps one decorative line from filling the output with errors.
Urdu documents people convert most often
The most common Urdu document is the CNIC, the national identity card, which carries a name, a thirteen digit number, a date of birth, and an address in a small printed layout. Domicile certificates, birth certificates, and education certificates follow a similar pattern: formal Urdu wording around names, dates, and reference numbers that people need as editable text for applications. A nikah nama, the marriage registration document, mixes printed Urdu with handwritten entries, so the printed headings usually read well while the handwritten names need checking by hand. Personal and official letters are another frequent case, along with pages from Urdu novels, poetry books, and school textbooks that students want to search or quote. Newspaper clippings are common too, especially for articles that exist only in print.
These documents share a practical pattern: the printed part is worth running through OCR, and the handwritten or stamped part is worth typing by hand. Keep the original photo safe so you can compare the output against it, and remember that an OCR copy of a certificate is a working copy for your own records, not a certified copy for official use. If the document carries a stamp over the text, crop a second, tighter pass over that area rather than accepting a guess from the first run.
Ligatures, joining, and dots: where Urdu OCR stumbles
Urdu letters change shape depending on where they sit in a word, at the start, in the middle, at the end, or alone, and most letters join to their neighbours. That joining is normal for readers, but it creates ligatures, groups of letters fused into a single flowing shape, and an engine must split those shapes back into letters before it can read them. Nastaliq makes this harder still, because its ligatures stack vertically and overlap. A word that looks like one graceful sweep to a reader can be several letters deep to a machine.
The dots are the second place where errors cluster. Urdu uses dots, called nuqta, to tell apart letters that share the same skeleton: one dot below, two dots above, three dots, and so on separate letters that would otherwise look identical. A soft photo or a compressed image can hide a dot, merge two dots, or turn a dot into a speck of noise, and the engine then chooses the wrong letter. Words can also run together when the space between them is narrow, so the output may join two words into one or split one word into two. The fix is mostly in the photo: sharp focus, good light, and a tight crop protect the dots and the joins. The rest is proofreading, best done by reading the output aloud, because a wrong letter usually makes the sentence sound wrong even when it looks plausible on screen.
Preparing Urdu print photos for better results
Good preparation matters more for Urdu than for English, because the script is dense with dots and joins. Lay the page flat and photograph it straight from above, with the phone parallel to the paper, so the lines stay level and the words do not lean. Bright, even daylight is ideal; a single lamp from one side casts shadows across the page and darkens one edge. If the page comes from a thick book, press the book open gently so the text near the spine flattens out, and photograph one page at a time rather than a two-page spread, because the curve near the spine bends the lines and confuses the engine.
Fill the frame with text and crop away the desk, your fingers, and any busy background before you run OCR. Stamps, seals, and handwritten notes in the margin should be cropped out of the first pass and handled separately, since they add shapes the engine may read as extra letters. A laminated CNIC deserves special care: tilt the card slightly until the glare moves off the text, or photograph it in soft daylight instead of under a direct lamp. Finally, check the photo at full size before you extract. If you cannot read the smallest dots yourself in the photo, the engine will not read them either, so retake the shot instead of running OCR on a blurry image.
A practical proofreading pass for Urdu output
Treat the OCR result as a draft and give it one careful pass before you use it. Read it line by line against the original image, from the top right of the page, and check names first, because a name has no context to catch a wrong letter. Then check every number: CNIC numbers, dates, and amounts should be compared digit by digit, and remember that Urdu documents may use Eastern Arabic numerals, Western digits, or a mix of both in one document. Watch for words that were joined or split, and for dots that moved a letter to a different word entirely. Reading the text aloud helps, because Urdu sentences have a rhythm, and a misread word usually breaks it.
Keep a short list of the confusions you see most often on your own documents, such as similar letters swapping or common words losing a dot, and check for those first on the next page. If a paragraph comes back badly garbled, do not keep re-running the whole page. Crop that paragraph alone, run it as its own pass, and compare the two results. Two short passes on a hard paragraph usually beat one long pass on a full page, and the time you spend proofreading is far less than the time you would spend retyping the page from scratch.
Related tools and guides
Need العربية too? Open Arabic OCR. Formats: JPG to text, PNG to text, screenshot to text. Guides: how to extract text from an image, best free OCR tools. Home: image to text converter.
Sources & further reading
- Tesseract OCR documentation, engine overview and language support
- Tesseract tessdoc, accuracy factors and training data notes
- Tesseract.js, browser OCR used on this page
Try our OCR tools
Same private browser OCR. Pick the page that matches your language or file type.
- Image to Text (Home)Free private OCR for English, Urdu, and Arabic images.
- Arabic OCRConvert Arabic images to editable text privately.
- Screenshot to TextPull text from error messages, chats, and receipts.
- JPG to TextOCR for JPEG camera photos and scans.
- PNG to TextOCR for sharp PNG screenshots and scans.