Worked example: image in, text out
Below is a simple sample card with clear Arabic print (plus one English line). Drop a similar JPG or PNG into the tool above, keep language set to Arabic, and you should see editable text close to the sample output. Real photos vary; this shows the intended workflow, not a promise of perfect OCR Arabic.
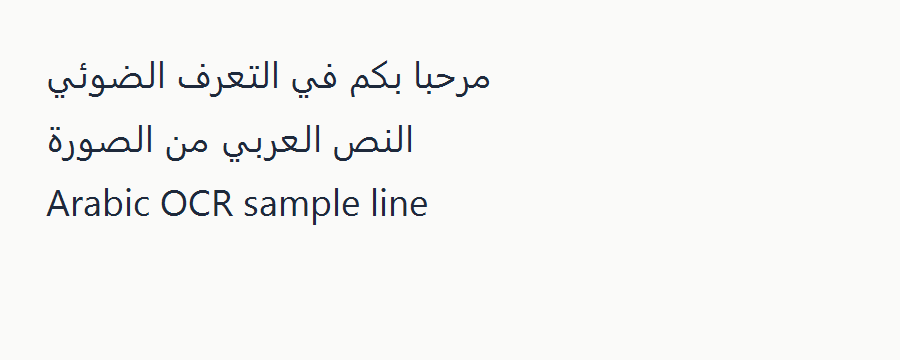
Expected OCR output (approx.):
مرحبا بكم في التعرف الضوئي
النص العربي من الصورة
Arabic OCR sample line
Arabic OCR online without cloud uploads
Searching for arabic ocr, ocr arabic, or image to text arabic usually means you need editable العربية from a form, textbook page, or sign, without shipping the photo to a remote API. Photo2Text keeps pixels on your machine: select Arabic, load a clear JPG, PNG, or WebP, and run Extract. Models load only when you ask for recognition.
إذا كنت تحتاج تحويل صورة إلى نص عربي، اختر اللغة العربية ثم اضغط Extract. الجودة تعتمد على وضوح الصورة والإضاءة.
Accuracy notes for OCR Arabic
- Printed Naskh-like fonts beat ornate calligraphy.
- Even light and high contrast help more than higher megapixels alone.
- Diacritics are often missing in everyday print; expect gaps.
- JPG to text Arabic is fine for phone cameras if compression is light.
- Always proofread before legal, medical, or financial reuse.
Arabic documents people convert most often
Arabic OCR is most useful on everyday official paper. National ID cards and residence permits carry a name, an ID number, a date of birth, and an expiry date in a small, dense layout. Birth, marriage, and graduation certificates carry formal wording, names, and dates that people need as editable text for forms and records. Employment and rental contracts run to several pages of printed Arabic, and official letters from government offices and schools usually follow a fixed letterhead layout with a reference number and a date at the top. Textbooks and study notes are another common case: a student photographs a page and wants the paragraph as text to search, translate, or quote. Each of these documents shares the same need. The text is printed, the layout is regular, and the reader wants an accurate copy without retyping every line by hand.
Before you run OCR on an official document, check what the document allows. Some offices only accept certified copies, and an OCR transcript is a working copy, not a certified one. For private use, such as filling a form, searching a contract, or archiving a certificate, an OCR copy is practical. Keep the original image safe, because you will compare the output against it during proofreading. If the document carries a stamp, a signature, or a seal over the text, expect the words under the stamp to be the hardest part of the page. Crop a second, tighter pass over that area if the first result is unclear.
Naskh and other Arabic print fonts
Most modern Arabic books, newspapers, and official forms are printed in a Naskh style font. Naskh letters sit on a clear baseline, the shapes are regular, and the spacing between words is even, which is why OCR engines handle it best. Headings often use a heavier or bolder cut of the same style, and bold text usually reads well because the thicker strokes survive compression. Older books may use a traditional typeset style with tighter spacing and thinner strokes, which needs a sharper image and a closer crop.
Decorative and calligraphic styles are a different story. Thuluth and Diwani lettering, the flowing styles used on certificates, mosque signs, and ornamental headings, stretch and stack letters in ways that break the usual letter shapes. An OCR engine trained on print will often return fragments or nothing at all from a calligraphic line. Handwriting varies even more, because each writer joins letters differently and the dots may sit far from their letters. If a page mixes a plain printed body with a decorative heading, run OCR on the body first and type the heading by hand. That split saves time and avoids a page of errors from one ornamental line.
Diacritics: the small marks that change meaning
Arabic short vowels and other pronunciation marks, called tashkeel or harakat, appear as small strokes above and below letters. A fatha, damma, or kasra marks a short vowel, a shadda doubles a consonant, and a sukun marks the absence of a vowel. Most everyday Arabic print leaves these marks out entirely, and readers fill in the vowels from context. That is normal for newspapers, contracts, and forms. OCR engines therefore expect unvocalized text, and their language models use word context to choose the right reading.
Problems start when the marks are present but faint. Quranic text, childrens school books, and classical poetry are fully vocalized, and every line carries many small marks. A low resolution photo can blur a fatha into a dot or merge a shadda with the letter below it, and the engine may then read a different word or drop the mark and return the bare consonants. If your document is fully vocalized, photograph it at the highest quality you can, keep the lighting even, and expect to restore missing marks by hand during proofreading. For ordinary unvocalized print, the practical rule is simpler: if the photo is sharp, the missing vowels are not the problem. Blurry dots and broken letter joins cause far more errors than absent diacritics do.
Reading right to left: line order and proofreading
Arabic reads right to left, and that changes how you check OCR output. Lines still run from the top of the page to the bottom, but within each line the first word sits at the right edge. A two-column Arabic page usually places the first column on the right, which is the opposite of an English layout. Tables flip too: the first column of an Arabic table is normally on the right, and numbers inside the table may still run left to right. Mixed content is common, so a line can contain Arabic words, a Western date, and an English brand name in the same sentence, and the engine must switch direction several times inside one line.
When you proofread, start at the top right and move left, then down to the next line. Check the order of items in a list, because an engine can return the items in the wrong sequence when the layout is crowded. Pay special attention to dates, amounts, and reference numbers, since a reversed digit order changes the meaning completely. If a table comes out scrambled, crop one column at a time and run each column as its own pass. That is slower, but a table read column by column is far easier to verify than a table whose cells were merged in the wrong order.
Worked example: reading an Arabic ID card step by step
Take a national ID card as a worked example. The card is small, the print is dense, and almost every field matters, so it is a good test of careful Arabic OCR. Lay the card flat on a plain surface and photograph it straight from above, with the phone parallel to the card, so the edges stay square and the lines do not tilt. Use bright, even light and avoid the flash, because a laminated card reflects glare across the middle of the text. Fill the frame with the card and crop away the table or desk around it before you run OCR.
Run the first pass with the language set to Arabic. The name field usually comes first and is the longest line, so read it first and compare it letter by letter with the card, watching for dots that decide between similar letters. The ID number is next: count the digits and check each one, because a single wrong digit makes the number useless. Dates follow, and here you should confirm whether the card uses the Hijri calendar, the Gregorian calendar, or both, then keep the order of day, month, and year exactly as printed. The expiry date deserves the same care. Finally, look for small print at the bottom of the card, such as an issuing authority line, and run a second cropped pass on it if the first result skipped it.
Expect three kinds of error on a card like this. Similar letters may swap where dots are faint. Digits may be confused where the print is small, especially between Arabic-Indic and Western digit shapes. And a stamp or hologram overlapping the text may hide a word entirely. None of these is a reason to trust the raw output. Read the result against the card, fix the fields by hand, and only then copy the text into a form or a record. That short proofreading pass is what turns a fast OCR draft into a reliable copy of an official document.
Related tools and guides
Also need اردو? Open the Urdu OCR page. Camera JPEGs: JPG to text. UI captures: screenshot to text or PNG to text. Beginners: how to extract text from an image. Comparisons: best free OCR tools. Arabic guide: Arabic OCR guide. Home: image to text converter.
Sources & further reading
- Tesseract OCR documentation, open-source OCR engine overview
- Tesseract tessdoc, languages and accuracy considerations
- Tesseract.js, browser OCR used on this page
Try our OCR tools
Same private browser OCR. Pick the page that matches your language or file type.